welcome to my corner of the internet

Blog

The full feed. Prefer a quick overview? Browse the archive →

What Building Organize Tabs 2.0 with Claude Code Actually Looked Like

Yesterday I shipped Organize Tabs 2.0, a rewrite of a Chrome extension I had been using daily since 2020. I said I would write up how it was built, because most of it was built with Claude Code, and the interesting part was not the speed.

Here is what the two weeks actually looked like.

The shape of it

Started September 29, with a request to analyse the old code and tell me what was wrong with it
Merged October 9, pull request #9, nine commits, +4,814 / −673 lines
Published October 10 on the Chrome Web Store
Follow-up October 11, 2.1.0 with a customizable layout, after a day of using 2.0

The old extension was one 520-line file. The new one is about 3,500 lines of source, of which 750 are a pure module with no Chrome API calls, 29 unit tests, and an end-to-end suite of 48 checks that drives the real extension in a headless browser. Nineteen duplicate rules, an options page, a demo video that records itself.

Calendar time was two weeks. Hands-on time was a handful of evenings, most of them spent reading, deciding and testing rather than typing.

It started with a code review of my own code

The first thing I asked for was not code. I pasted a screenshot of the popup, listed what I liked and what annoyed me, and asked what I should improve.

The answer was more useful than I expected, because it started with bugs I did not know I had. “Bring All Windows To Front” had never worked: the action table used an object shorthand instead of a callback: key, and the handler incremented a const. The popup ran all the tab logic itself, and Chrome closes a popup the moment a new window is created, so consolidating tabs was killing its own promise chain halfway through. Collate created windows in parallel and each one ran a global cleanup that could close a sibling before its tabs arrived.

I had worked around all three for years without knowing why they were flaky. That review set the architecture for the rewrite: every tab operation runs in the service worker, the popup only sends messages, and window creation is sequential.

What I did and what it did

I want to be precise about this, because “built with AI” covers a lot of ground.

I supplied the problem. The habit of opening every pinged link and using tabs as a to-do list. The specific duplicate shapes: a pull request and its Files tab, a Jira issue and its board link, a LinkedIn profile and its Experience page. The fact that I am usually on a Google Meet while tidying.

I made the calls. Vanilla JavaScript, no build step, no dependencies, same as the original. Tab groups instead of windows. Favorites and reordering instead of a fixed list. The name of the sandbox. Version 2.0 rather than 1.0, after discovering the published version was 0.9 and not the 0.8 in git.

It drafted nearly everything. The URL normalizer and rule engine, the service worker, the popup, the options page, the test suites, the CI workflow, the store listing copy, the demo recorder. First drafts of all of it were on disk within hours, and most survived with edits rather than rewrites.

I used it and said no. This is where the real work was.

The real work was constraints

Every design rule the extension now has came from me using a draft and objecting.

I ran the first version against my real hundred tabs. Sort moved a pinned tab. Consolidate dropped every tab out of its group, because that is what Chrome does when a single tab changes windows. I said: never move a pinned tab, and never break a group. The second rule turned into the most intricate code in the extension, which moves whole groups between windows with the tab groups API, merges into a same-named group at the destination, and rebuilds the group when only part of it moves.

I said: I am on a call while doing this. That became a rule that windows holding a meeting or playing media are primary, and Consolidate and Split leave them alone, plus a button to pull every meeting into its own window.

I said: I do not trust a button that closes forty tabs. That became a preview before every close, and an undo.

None of those were features I would have listed up front. They were refusals, discovered by use. Deciding what a tool must not do turned out to be the part only I could do, and it was the part that took the time.

Testing was the fun part

The pure module has a normal node --test suite, and adding a rule means adding a test with the URL variants that must collapse and one that must not. That is table stakes.

The end-to-end suite is the part I am pleased with. A script launches a headless Chromium with the extension loaded, connects over the DevTools protocol, seeds windows full of tabs, then calls every action and asserts on the resulting windows, groups and pinned state. It found things I would never have caught by hand:

  • Chrome for Testing ships built-in extensions with their own service workers, so matching on background.js picked the wrong one.
  • Headless Chrome reports several windows as focused at once, which exposed that Consolidate chose its target by the focused flag. It now prefers the window you invoked it from, which is better in real browsers too.
  • A video popped out into its own window lives in a popup-type window, and Chrome refuses to move tabs into or out of those. The first time I hit that was in my real browser, with a red error toast. The suite now has a popped-out YouTube window in it.

The same harness records the demo video. Each frame is a stage page composing a live map of the browser’s windows next to a screenshot of the popup, with a drawn cursor and a caption. No screen recorder, no editing, and I can re-record after any UI change with make demo.
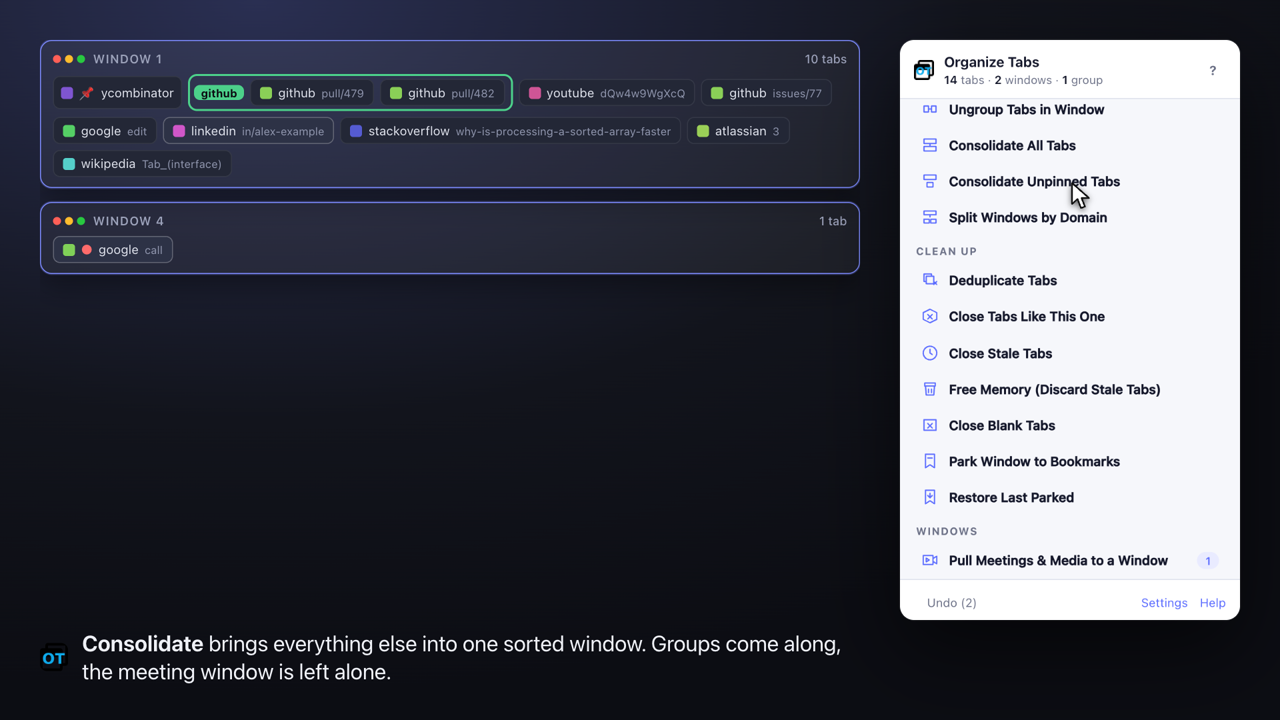
After consolidating: everything in one sorted window, the meeting in its own

The holodeck

Browser tests close and move tabs across every window. They cannot run against a profile I care about, and Chrome refuses to start a second instance on a profile that is already open anyway.

So every run uses a throwaway profile under ~/.holodeck/. The interactive one is named “🧪 holodeck” in the browser’s profile chip so I always know where I am. The automated ones are created fresh and deleted after each run. The rule, written into the repo’s AGENTS.md, is that humans and AI agents may create, inspect and destroy anything under that directory without asking.

We brainstormed names. Danger room was the runner-up. Holodeck won because it is one word, and because “computer, end program” is exactly what make dev-clean does. The convention has already spread to my other projects.

The review that found ten bugs

The day before release I asked for one more pass: an adversarial review of the whole pull request, assuming it was wrong until proven safe.

It came back with ten real defects, all in code the same tool had written days earlier. The worst: with auto-deduplicate on, Undo reopened the tabs it had closed, and auto-dedupe immediately closed them again as fresh duplicates. Undo was a no-op. Another: a duplicate closed in an incognito window, after that window was gone, would be reopened by Undo in a normal window, writing a private URL into history. Another: when settings overflowed the sync quota and fell back to local storage, the next load read the stale sync copy and silently reverted.

I would not have found any of those before shipping. All ten were fixed, with tests, in an afternoon.

The lesson is not that the tool is unreliable. It is that drafting and reviewing are different activities, and you have to ask for the second one explicitly. The same model that wrote the bug found the bug when its job was to find bugs.

The mundane parts were still mundane

For balance, the things that went sideways had nothing to do with intelligence:

  • Google Chrome’s branded build silently stopped honouring --load-extension some versions ago, so the test harness defaults to Brave, with Chrome for Testing in CI.
  • My SSH agent started offering the wrong GitHub key, and a push failed mid-release with a permission error from an account I had forgotten existed.
  • The Chrome Web Store summary is the manifest description and is capped at 132 characters. Mine was 155.
  • Hacker News auto-killed my Show HN comment for having links in it.

An AI pair does not make any of that go away. It does make it cheaper to work around, because the context is already loaded and the fix is a sentence.

What I would tell someone starting

  1. Start by asking for a review of what you have. The bugs in my old code shaped the new architecture more than any feature request.
  2. Decide the constraints yourself, by using it. The tool will happily build a feature. It cannot know that your meeting window is sacred until you say so.
  3. Build the test harness early and make it real. A browser-level suite caught every platform quirk. Unit tests alone would have caught none of them.
  4. Ask for an adversarial review before shipping, as a separate step. Then fix everything it finds, because it will be right more often than you are comfortable with.
  5. Give the agent a sandbox with a name. A clear place it may trash removes a whole category of hesitation, for both of you.

The extension is on the Chrome Web Store and on GitHub, where the AGENTS.md, the e2e harness and the demo recorder are all there to borrow.
Permalink & comments →

Organize Tabs 2.0: A Tab Deduper That Knows a Pull Request When It Sees One

I open every link I get pinged. Slack, email, GitHub notifications, calendar invites, all of it. The open tabs become my to-do list, and closing one means I dealt with it. It is a terrible system that I have no intention of giving up.

By Friday that is somewhere north of a hundred tabs across several windows, on each of the machines I work from. The same pull request is open three times, as /pull/482, /pull/482/files and /pull/482/checks. The same LinkedIn profile is open twice, once on the profile and once on the Experience page. A Jira issue is open as /browse/ENG-1201 and again as ?selectedIssue=ENG-1201 on a board. And the browser is quietly eating memory.

Back in 2020 I wrote a small Chrome extension called Organize Tabs to deal with this. It could collate tabs into windows by domain, consolidate them, sort them, and deduplicate exact URLs. I have used it every day since. It was also, if I am honest, a thin wrapper around the Chrome API with a Bootstrap button list, a dedupe that only matched exact URLs, and a few bugs I had learned to work around.

This week I rebuilt it. Version 2.0 is live on the Chrome Web Store, free and open source.

Duplicates, even when the URLs differ

Every tab deduper I tried compares URLs as strings, so none of the cases above count as duplicates. The new one works in two stages.

First, generic normalization: http and https are the same, so is www., the #fragment is dropped, trailing slashes are ignored, tracking parameters like utm_source and fbclid are stripped, and the remaining query parameters are sorted.

Second, a list of rules. Each rule is a regular expression tested against the URL and a key template. If a rule matches, the key is what gets compared, not the URL:

{
  "name": "GitHub pull request",
  "match": "^https?://github\\.com/([^/]+)/([^/]+)/pull/(\\d+)",
  "key": "github:$1/$2/pull/$3"
}

With that rule, every subpage of a pull request is the same tab. Nineteen rules ship by default, for GitHub, Bitbucket, GitLab, Jira, Confluence, LinkedIn, YouTube, Google Docs and Drive, Notion, HubSpot, Slack, Figma, Amazon, Stack Overflow, Reddit and X. They are editable JSON in the settings page, with a tester that shows which rule a pasted URL hits and the key it produces. If your site’s URLs should collapse and do not, it is a ten-line pull request.

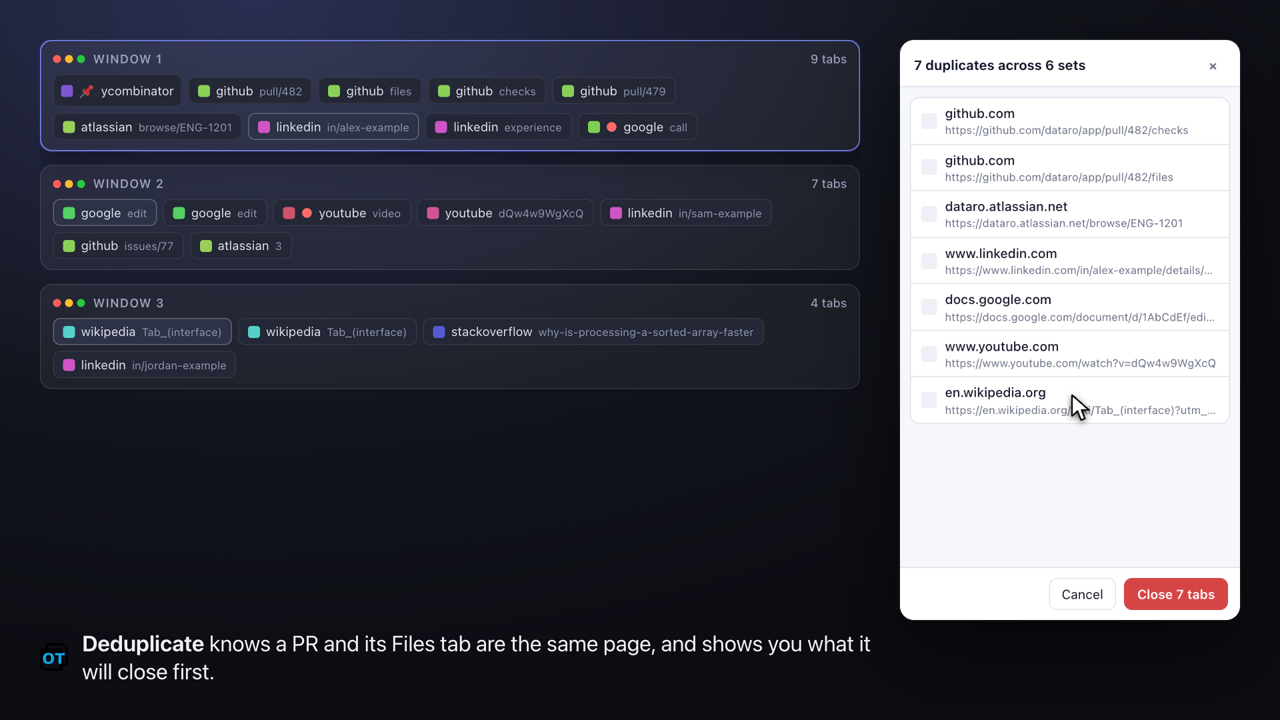
The dedupe preview, listing seven duplicates across three windows before anything is closed

Which copy survives matters too. The pinned one wins, then the active one, then the most recently viewed. Nothing closes without a preview, and the last close can always be undone.

There is also an opt-in auto-deduplicate: open a link that is already open somewhere, and the new tab closes itself and takes you to the existing one. For someone with my habits this is the feature that stops the pile from forming in the first place.

Close tabs like this one

The old “Close all tabs from this domain” was a shotgun. Sometimes I want to close every LinkedIn profile I have opened, but not the feed. Sometimes every pull request, but not the issue I am reading.

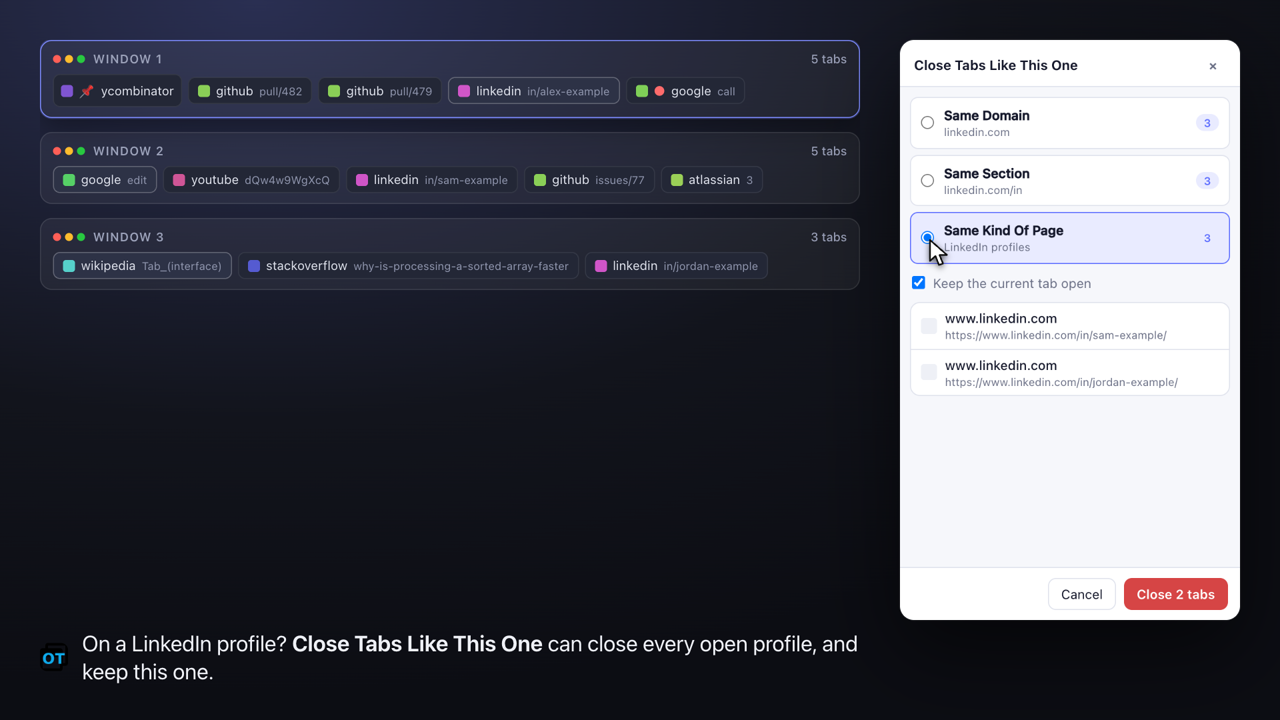
The same rules power a scoped close. From any tab you get three choices: the same domain, the same section of the site such as github.com/myorg, or the same kind of page, which means every tab matching the same rule. There is a toggle to keep the tab you are on, and the preview shows exactly what will go.

Close Tabs Like This One, with the "same kind of page" option selected on a LinkedIn profile

Pinned tabs and tab groups are sacred

The old version would happily sort pinned tabs into the middle of a window, and consolidating windows dropped every tab out of its group, because that is what Chrome does when a single tab changes window.

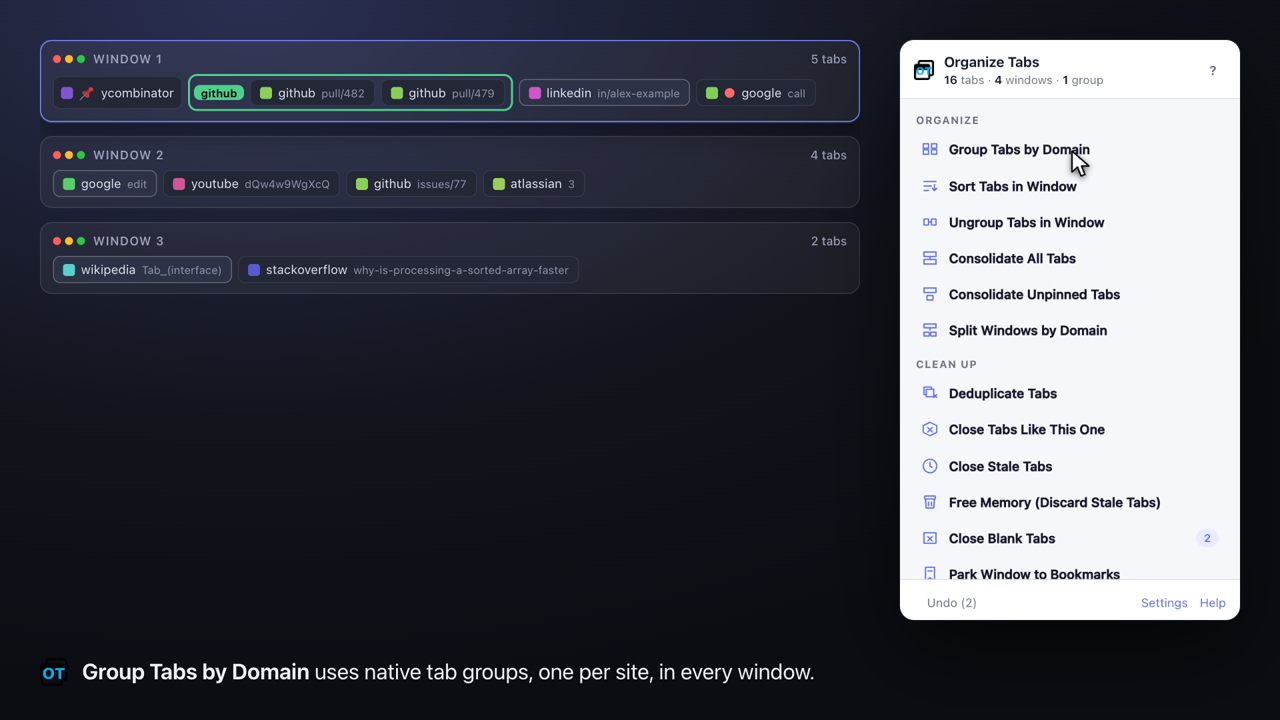
Now no action ever moves a pinned tab. Sort keeps groups contiguous and sorts them by name. Consolidate and Split move whole groups between windows with the tab groups API, and when the destination already has a group with the same name the incoming tabs join it. A new Group Tabs by Domain uses native groups instead of spawning windows, which is what the old “collate” really wanted to be.

After Group Tabs by Domain: a github group in the first window, pinned tab untouched

Meetings are left alone

I am usually on a call while tidying. The thing I wanted most was for cleanups to never pull the meeting out from under me.

A tab counts as media if it is audible, or if it is on a meeting or player page: Google Meet, Zoom, Teams, YouTube and a dozen others, editable like the rules. Pull Meetings & Media to a Window gathers all of them into one window with one click. Consolidate and Split then leave that window alone.

After consolidating: everything in one sorted window, the meeting in its own

The rest

  • Close stale tabs you have not looked at in N days, or free memory by discarding them without closing.
  • Park a window to a dated bookmark folder and close it, then restore it later as a tab group. Tabs as a to-do list, without the memory cost.
  • Settings and rules sync with the browser profile. Export and import JSON to move between profiles, or point the extension at a rules file you host and it refreshes on a schedule. I run this on a lot of machines and profiles, and this was a big one for me.
  • Keyboard shortcuts for every action, a duplicate count on the toolbar icon, a right-click menu, light and dark themes, inline help.

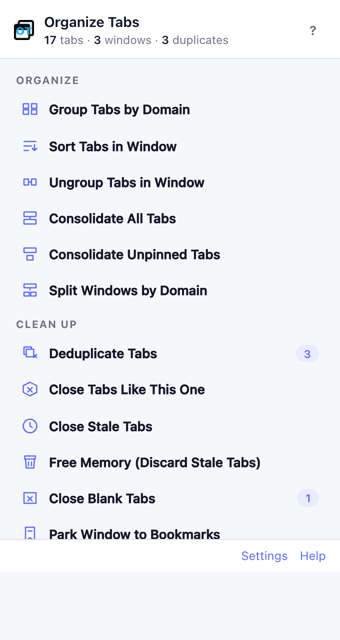
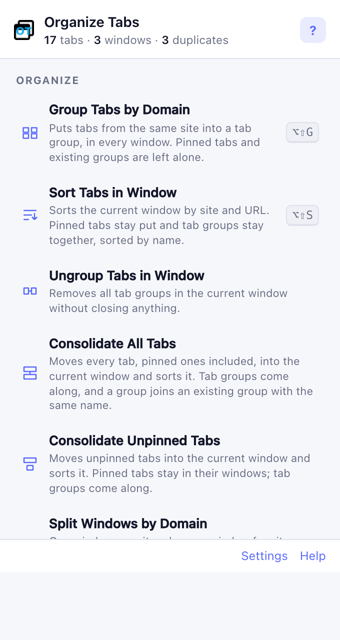
The popup The popup with inline help on

How it is built

Still vanilla JavaScript, Manifest V3, no build step, no dependencies. That was a deliberate constraint from the start and it held. The whole thing is a few files: a service worker that owns every tab operation, a pure module for the URL logic, a popup that only sends messages, and a settings page.

The pure module has a node --test suite. The part I am most pleased with is the end-to-end test: a script launches a real headless Chromium with the extension loaded, drives it over the DevTools protocol, seeds tabs, clicks every action, and asserts on the resulting windows, groups and pinned state. It runs in CI on every push with Chrome for Testing. The same harness records the demo video above, composing each frame from a live map of the browser’s windows next to the popup. No screen recorder, no editing.

Local browser testing never touches a real profile. Everything runs in what I have started calling the holodeck, a throwaway profile at ~/.holodeck/ that humans and AI agents can trash freely. make dev opens it with the extension loaded and two windows of sample tabs that hit every rule. That convention has already spread to my other projects.

Most of this was built pair-programming with Claude Code over a few days. The design calls were mine; the first draft of nearly every file, the test harness, and a review pass that found ten real bugs before release were not. I will write that up separately, because the interesting part was not the speed but how much of the work turned out to be deciding what the tool should refuse to do, like never moving a pinned tab.

Limitations

Chrome has no API for the tab strip’s right-click menu, so the actions live in the toolbar popup, the page context menu and keyboard shortcuts. Stale tab detection uses lastAccessed, which needs Chrome 121 or newer. Silent media detection is URL based, because telling a paused video from a playing one needs a content script, and I did not want one.

Get it

If you were using the old version, Chrome will ask you to accept a few new permissions, for tab groups, storage, bookmarks and alarms. Nothing leaves your browser; there is no tracking and no network request except the optional rules file you configure yourself.

Permalink & comments →

I Bought jonts.ai for My AI Döppelgänger

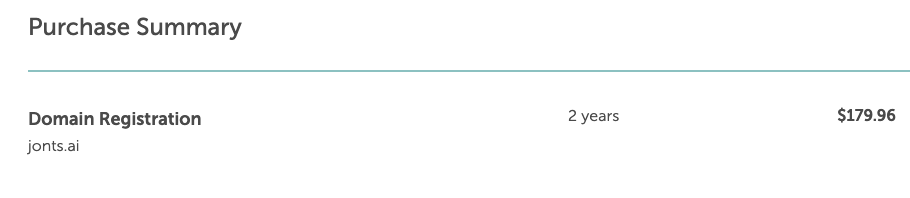
I did a very normal thing: I bought jonts.ai for 2 years for $179.96 so my AI alter ego could have a proper home.

Purchase summary showing jonts.ai domain registration for 2 years at $179.96

The site is intentionally tiny:

https://www.jonts.ai

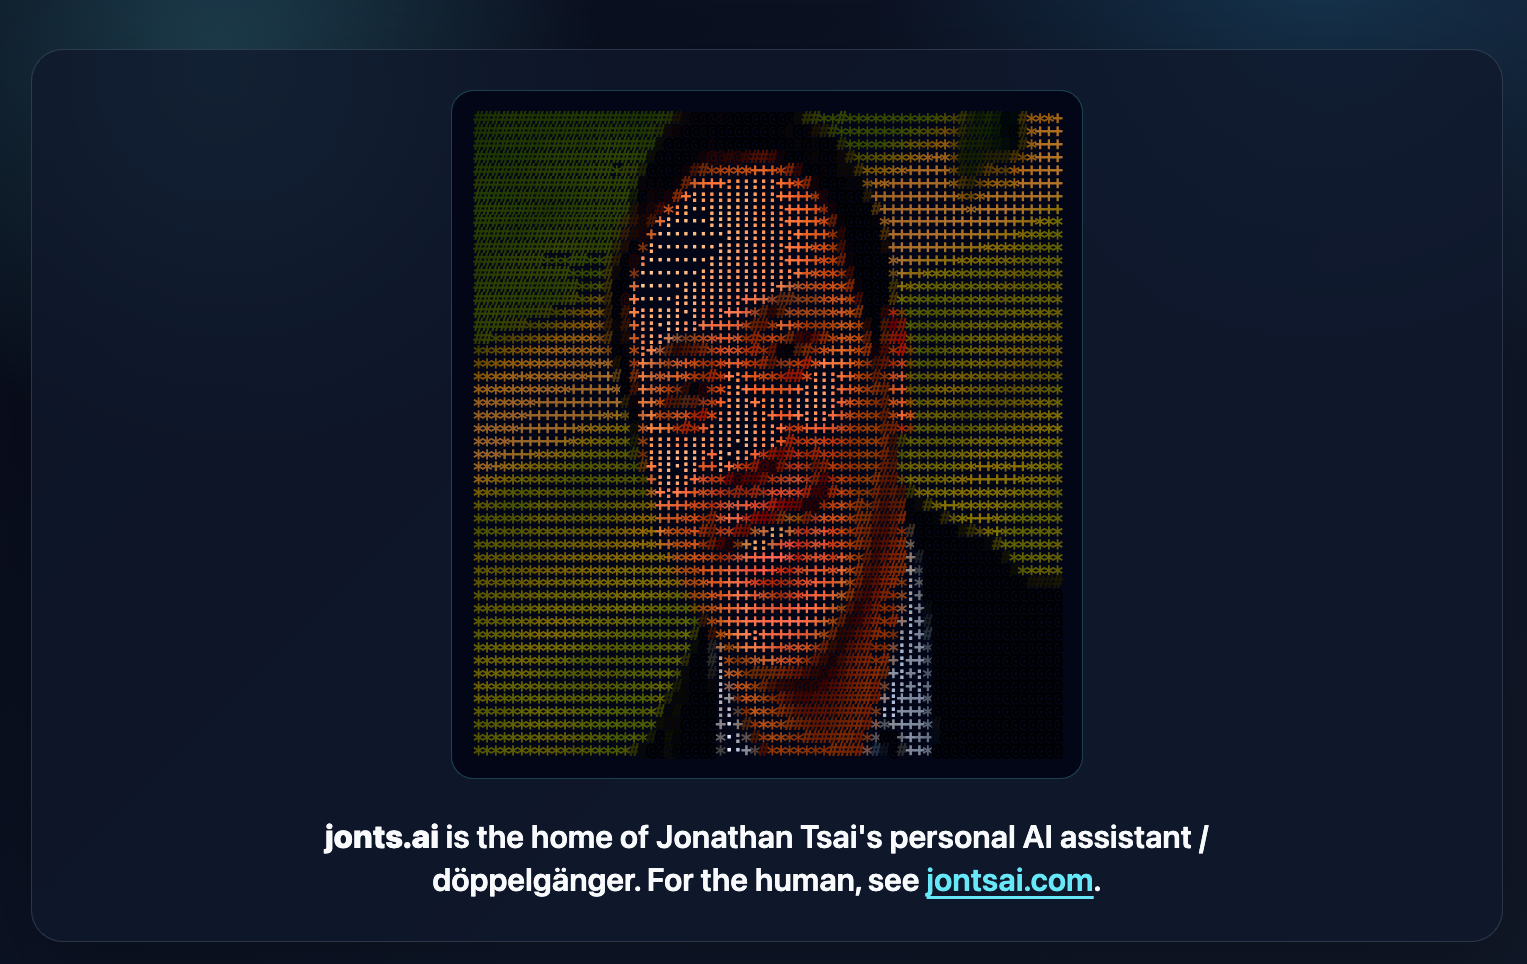
Screenshot of the jonts.ai landing page with a colored ASCII-art portrait

It says, simply:

jonts.ai is the home of Jonathan Tsai’s personal AI assistant / döppelgänger. For the human, see jontsai.com.

The project now lives under its own GitHub handle:

https://github.com/jonts-ai

The fun part is the portrait.

I used my GitHub avatar as the source image, then generated a colored ASCII-art rendering where each text glyph acts like a pixel. Up close, it is made of little characters. From a distance, it resolves back into a face. That felt like the right aesthetic for an AI alter ego: half identity, half terminal output.

There is no official pronunciation for jonts.ai yet. One possible rendition is “Jon T’s AI,” which is ridiculous enough that it might stick.

This is mostly whimsical, but it also marks something real: I am increasingly building with AI agents as persistent collaborators, not just one-off tools. Giving the assistant a public home, a GitHub handle, and a tiny bit of personality makes the whole thing feel more concrete.

For the AI: https://www.jonts.ai
For the human: https://jontsai.com

Permalink & comments →

The Hardest Pull Requests I've Ever Gotten Merged

Two of my pull requests were just merged into OpenClaw:

The commits that made it to main are here: github.com/openclaw/openclaw/commits/main/?author=jontsai

They were reviewed and merged by Pete Steinberger.

That still feels surreal to type.

I’ve been writing software professionally for more than two decades. I’ve worked on production systems, led teams, debugged gnarly incidents, reviewed a lot of code, shipped a lot of code, and lived through enough “simple changes” to know that simple rarely means easy.

And somehow, these were the hardest PRs I’ve ever had to work to get merged.

Even with AI.

AI Makes You Faster. It Does Not Lower the Bar.

This is the part I keep coming back to.

AI helped me move faster. It helped me explore the codebase, draft patches, iterate on tests, and respond to review feedback more quickly than I could have alone.

But the hard part was never just typing the code.

The hard part was judgment.

Does the change actually belong?

Does it preserve existing behavior?

Does it fit the architecture?

Does it handle the boring edge cases?

Does it make the product better for real users without creating maintenance debt for the people who have to live with it after you disappear?

In a serious open source project, velocity is useful, but velocity is not enough. The code still has to be right. The tests still have to earn trust. The implementation still has to match the shape of the project.

AI can increase your output. It cannot remove the responsibility to think.

The Bar Was High Because the Project Is Good

OpenClaw is large, fast-moving, and maintained by people with very high standards.

That is exactly how it should be.

Healthy open source projects do not stay healthy by accepting every plausible patch. They stay healthy because maintainers protect the product. They ask whether a change is correct, whether it is general enough, whether it introduces weird coupling, whether it creates future surprises, and whether it improves the system in a way that justifies the complexity.

When you are on the contributor side, that can feel brutal.

When you step back, it is also the reason the project is worth contributing to.

A low bar feels nice in the moment. A high bar makes you better.

My Edge: I Actually Live in the Weird Part

The reason I had anything useful to contribute was not that I sat down and decided to become an OpenClaw contributor.

It was that I use OpenClaw heavily through Slack.

That matters.

Slack is not a toy integration. Slack has threads, mentions, channel names, channel IDs, App Home behavior, command routing, formatting quirks, permission edges, and all the delightful chaos that shows up when real work happens in real conversations.

If you only read the code, some of those edges are invisible.

If you live inside the product every day, they become paper cuts.

Eventually, the paper cuts become clues.

One PR came from Slack channel read behavior around name-allowlisted channels and channel IDs. Another came from App Home command configuration not matching how the active command surface was supposed to work.

Neither one sounds glamorous.

Both matter if Slack is where you actually use the product.

That is the underrated path into open source:

Use something deeply enough that you can see the mismatch between how it is supposed to work and how it behaves in the wild.

Then fix one edge.

Then another.

Small Fixes Are Not Small Work

One of the humbling things about these PRs is that the end result was not some huge, cinematic feature.

They were fixes.

But good fixes in a mature project are not just “change the line that looks wrong.”

A good fix has to understand the surrounding contract. It has to avoid breaking other users. It has to be tested at the right layer. It has to be phrased in the project’s language. It has to survive maintainers asking, implicitly or explicitly, “Are you sure?”

That process forces clarity.

You discover which assumptions were yours and which ones were actually true.

You discover whether you understand the project or merely understand the symptom.

You discover that the difference between “works for me” and “belongs in main” is enormous.

The Real Lesson

I have shipped bigger features.

I have written more complex systems.

I have had code run in products with more users.

But I do not think I have ever felt prouder of an open source contribution.

Not because the diff was the biggest.

Because the bar was the highest.

That is the part that made it meaningful.

Getting through that review process made me a better engineer. It reminded me that even in the AI era, maybe especially in the AI era, craft still matters. Taste still matters. Judgment still matters. Respect for the maintainers still matters.

And if you want to contribute to open source, my advice is simple:

Do not start by looking for a heroic project.

Start by using something until you understand where it hurts.

Then fix the hurt.

Carefully.

Huge respect to Pete and the OpenClaw maintainers. The bar is brutal in the best possible way.

Permalink & comments →

Building Mission Control for My AI Workforce: Introducing OpenClaw Command Center

The Backstory

I’m not a “script kiddie” or weekend hobbyist. I’m a UC Berkeley-trained Computer Scientist with over two decades of professional experience in Silicon Valley. I joined Iterable and EasyPost after their Series A rounds — both are now unicorns. At EasyPost, I managed 4 teams totaling ~20 engineers and delivered 8 figures of revenue.

I know what production systems look like at scale.

A few months ago, I read Peter Steinberger’s seminal post about shipping at inference speed. steipete is possibly one of the greatest programmers of this generation, and ClawdBot (now OpenClaw) was immediately on my radar. I was already racing to build my own AI Agent Swarm orchestrator — but I thought, “He’s good, but can I trust him?”

Then, three weeks ago, OpenClaw went viral. I went all-in. I’ve been hacking until 4am, 5am every night building out what I call the OpenClaw Command Center.

This year alone: After switching to Claude Code, I got a ~20x productivity boost. After adding OpenClaw, I got another 50x on top of that.

The math: 1000x productivity multiplier. That’s not hyperbole. That’s my lived experience.


What I’m Running Right Now

  • 5 OpenClaw master instances — one for each domain of my life
  • 10 satellite agents — specialized workers
  • 1 “Godfather” orchestrator — coordinates everything
  • 20+ scheduled tasks per instance — running 24/7
  • Hardware: Mac Studio M2 Ultra + Mac Minis + MacBook Pro + VirtualBox VMs on top of old Windows host

Each OpenClaw instance is a “GM” (General Manager) that oversees one aspect of my personal or professional life. They advance my goals and keep me locked in — even when I’m sleeping.

I’m literally coding at the gym on my phone… via Slack… in between bench pressing 315 lbs.

The possibilities are endless. AGI is here.


See It In Action


The Vision: Bring the Work to Where Humans Are

I’ve seen the mockups and prototypes online — “the future of work” dashboards, agent orchestration UIs, yet-another-SaaS-tool. That’s the wrong direction.

Here’s the thing: humans are already in Slack.

I’ve worked at companies with dozens, hundreds, even thousands of Slack channels. That’s where work happens. That’s where context lives. That’s where people communicate.

So instead of building another tool that forces context-switching, I asked: what if I brought the visibility to where I already am?

The agents live in Slack threads — that’s their native habitat. Command Center doesn’t replace Slack; it gives you the bird’s-eye view you’re missing. It’s the air traffic control tower for your AI workforce.

Think of it like a Starcraft command center (yes, I’m dating myself):

  • High APMs (actions per minute)
  • Lots of AI workers running in parallel
  • Ensure all agents are unblocked
  • No idle workers sitting around

You need to see everything at once to coordinate effectively.


What I Built

Real-Time Visibility

The dashboard shows everything that matters:

  • Session monitoring — Every active AI session, with model, tokens, cost, and context
  • LLM Fuel Gauges — Never get surprised by quota limits (we’ve all been there)
  • System Vitals — CPU, memory, disk — is your machine the bottleneck?
  • Cost Intelligence — Know exactly what your AI workforce costs

Topic Tracking (Cerebro)

One of the most powerful features is automatic conversation organization. I call it Cerebro — inspired by the machine that augments Professor X’s innate telepathic abilities.

My setup: multiple Slack channels, one per project. Within each channel, one thread per feature. Cerebro auto-detects topics from threads and organizes them.

Each thread becomes a trackable unit of work:

  • All topics across your workspace
  • Thread counts per topic
  • Jump directly into any conversation

This is possible because OpenClaw integrates deeply with Slack threading. Every message goes into the right thread, every thread has a topic, every topic is visible in the dashboard.

I worked really hard to allow OpenClaw to “stay focused” on topic. That discipline pays dividends.

Scheduled Tasks (Cron Jobs)

AI agents shouldn’t just react — they should proactively check on things, generate reports, clean up stale work. The cron dashboard shows:

  • All scheduled tasks
  • Run history
  • Manual triggers
  • Configuration at a glance

Privacy Controls

When demoing or taking screenshots, you can hide sensitive topics with one click. Learned this the hard way — you don’t want to accidentally share internal project names in a public post.


The Technical Details

Zero Dependencies, Instant Startup

Command Center is deliberately minimal:

  • ~200KB total — dashboard + server
  • No build step — runs immediately
  • No React/Vue/Angular — vanilla JS, ES modules
  • Single unified API endpoint — one call gets all dashboard data

Why this approach:

  1. AI agents can understand and modify it easily
  2. No waiting for webpack/vite compilation
  3. Works in any environment with Node.js

Security-First

Since this gives visibility into your AI operations, security was non-negotiable:

  • Localhost by default — not exposed to network
  • No external calls — zero telemetry, no CDNs
  • Multiple auth modes — token, Tailscale, Cloudflare Access
  • No secrets in UI — API keys never displayed

Real-Time Updates

The dashboard uses Server-Sent Events (SSE) for live updates. No polling, no websocket complexity. State refreshes every 2 seconds, cached on the backend to stay responsive under load.


The Philosophy: Use AI to Use AI

Here’s the key insight that changed everything:

Recursion is the most powerful idea in computer science.

Not loops. Not conditionals. Recursion — the ability for something to operate on itself. And the same principle applies to AI:

Use AI to use AI.

Think about it: Why are you manually configuring your AI agents? Why are you manually scheduling their work? Why are you manually routing tasks to the right model?

The agents should be doing that. The meta-work of managing AI should itself be done by AI.

This is how I gain an edge — not just over people still coding manually, but over vanilla OpenClaw users. I built the infrastructure for AI to optimize its own operations.


Advanced Job Scheduling (What’s Already Working)

After years of production experience with Spark, Airflow, Dagster, Celery, and Beanstalk — each with their own strengths and painful limitations — I had strong opinions about what an AI-native scheduler should look like.

I pulled concepts straight from CS162 (Operating Systems): multi-threading primitives, semaphores, mutex locks, process scheduling algorithms. These aren’t academic exercises — they’re exactly what you need when orchestrating dozens of AI agents competing for limited resources.

The scheduling primitives I’ve built:

  • run-if-idle — Execute only when system has spare capacity (no resource contention)
  • run-if-not-run-since — Guarantee freshness: “hasn’t run in 4 hours? run now”
  • run-at-least-X-times-per-period — SLA enforcement: “must run 3x per day minimum”
  • skip-if-last-run-within — Debouncing: “don’t spam if we just ran 10 min ago”
  • conflict-avoidance — Greedy algorithm prevents overlapping heavy jobs
  • priority-queue — Critical tasks preempt background work

This isn’t theoretical. It’s running in production right now across my 5 master instances and 10 satellite agents.


Intelligent Quota Management

I’m on the $200/month Claude Code Max plan. Without optimization, I’d blow through my weekly quota by Wednesday and be paying overage the rest of the week.

Instead, I’ve never paid a cent of Extra Usage. Conservatively, this system saves me at least $10,000/month in what would otherwise be API costs and overage charges.

How? The scheduling system is quota-aware:

  • It knows when my weekly quota resets (Saturday night 10pm)
  • It tracks current usage percentage via the API
  • It batches low-priority work for off-peak hours

Real example: It’s Thursday night. I’ve used 75% of my weekly quota. The scheduler sees this and thinks: “We have 25% left, 2.5 days until reset, user is asleep. Time to burn cycles on background work.”

So it wakes up my agents and has them iterate on unit tests — grinding my monorepo toward 100% code coverage while I sleep. Work that needs to get done, but doesn’t need me present.

By the time quota resets Saturday, I’ve maximized value from every token. Then Sunday morning I have a full fresh quota for the real creative work.


LLM Routing: Right Model for the Job

Not every task needs Claude Opus 4.6.

I built a routing layer that matches tasks to models:

Task Type Model Why
Code review, complex reasoning Claude Opus 4.6 Worth the tokens
Boilerplate, formatting, tests Local models (Qwen, Llama) Fast, free, good enough
RAG retrieval, embeddings Local Zero API cost
Documentation Claude Sonnet Sweet spot

The router examines the task, estimates complexity, and picks the appropriate model. Heavy thinking goes to the heavy model. Routine work stays local.

This is “Use AI to Use AI” in action — I didn’t manually tag every task. The routing agent figures it out.


What’s Next

Multi-Agent Orchestration

The real power unlocks when agents work together:

  • Swarm coordination patterns
  • Structured handoff protocols
  • Specialized agent routing (SQL tasks → SQL agent)
  • Cross-session context sharing

Voice Harness

Next, I’m working on STT/TTS integration so I can orchestrate my agents with just my voice — while I’m out walking my dogs, playing basketball, lifting weights. The keyboard becomes optional.


Try It Yourself

Command Center is open source and free:

# Via ClawHub
clawhub install jontsai/command-center

# Or git clone
git clone https://github.com/jontsai/openclaw-command-center
cd openclaw-command-center
node lib/server.js

Critical setup: Enable Slack threading in your OpenClaw config:

slack:
  capabilities:
    threading: all

This is what enables proper topic tracking.


The Bigger Picture

We’re at an inflection point. AI agents aren’t just tools anymore — they’re becoming teammates. And like any team, you need visibility, coordination, and management.

Command Center is my answer to: “How do I actually manage an AI-native life?”

It’s not the final answer. It’s the foundation I’m building on. And I’m excited to share it with the community.


OpenClaw Command Center is MIT licensed. Star it on GitHub, try it out, and let me know what you think.

Links:

Permalink & comments →